Announcing Our Astro Migration & Rebrand
Why we are porting our enterprise retrieval infrastructure site to Astro and preparing our connector developer ecosystem.
Updates, technical notes, and connector standards from the retrieval team.
Why we are porting our enterprise retrieval infrastructure site to Astro and preparing our connector developer ecosystem.
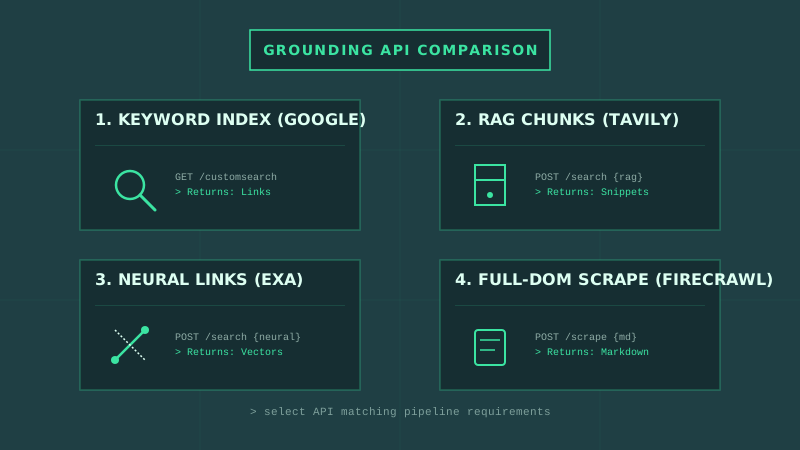
Why wrapping standard keyword search APIs is insufficient for RAG pipelines, and how Tavily, Exa, and Firecrawl handle text grounding differently.
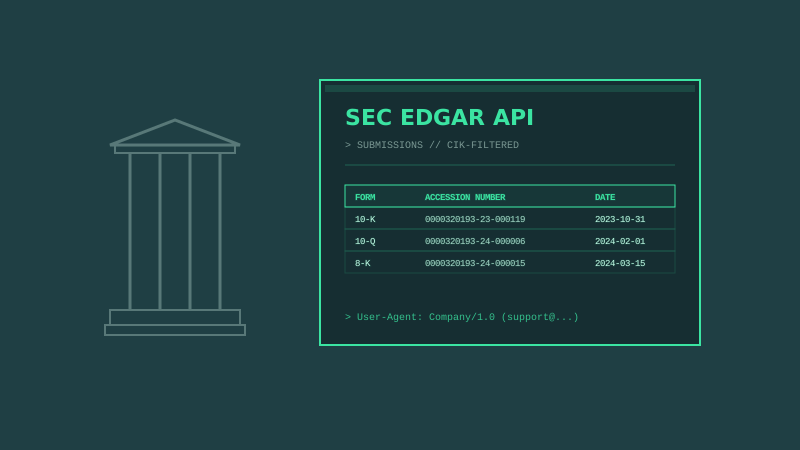
A guide to programmatically retrieving corporate filings, quarterly reports, and metadata from the SEC API.
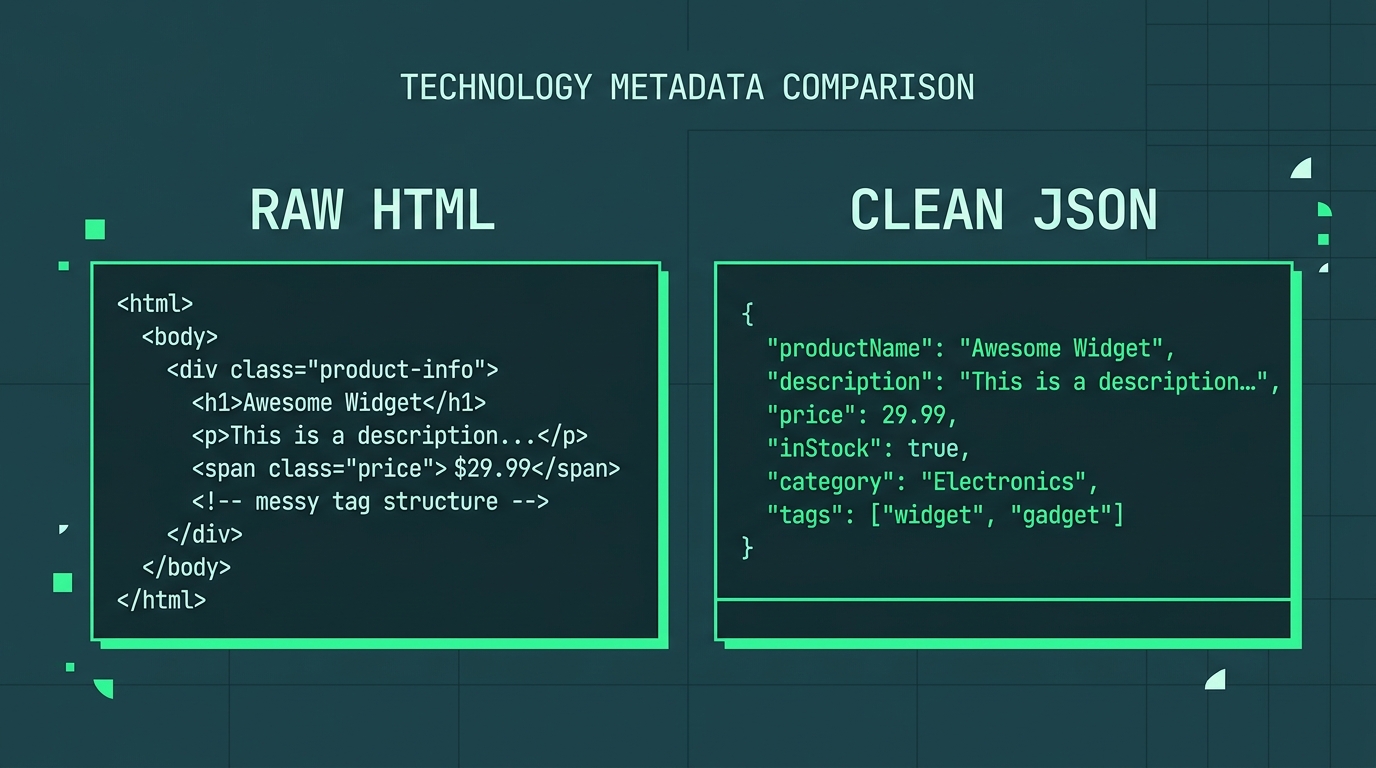
AI agents in regulated industries cannot make decisions based on raw text chunks. Here is how structured metadata enables deterministic reasoning.
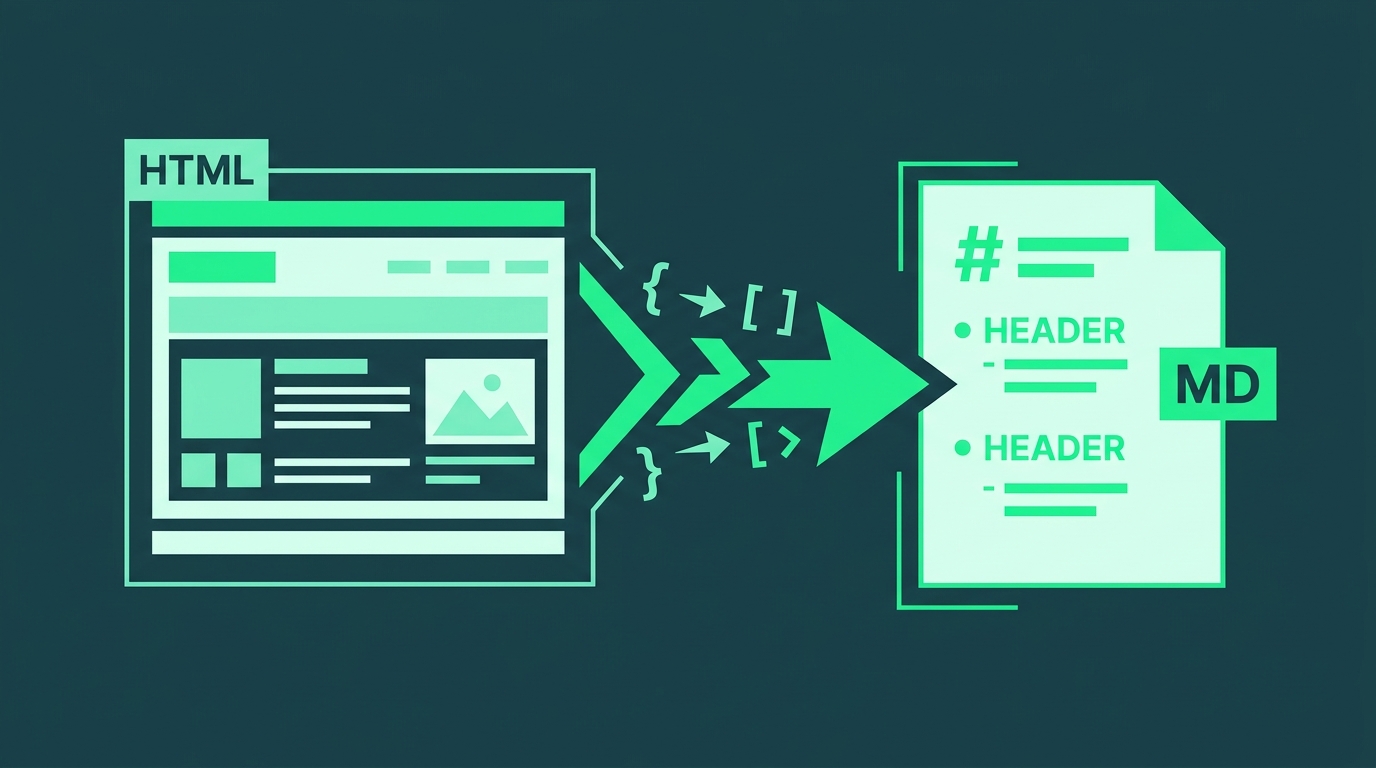
An open-source Python library designed to crawl JavaScript-rendered websites and output clean Markdown for RAG applications.
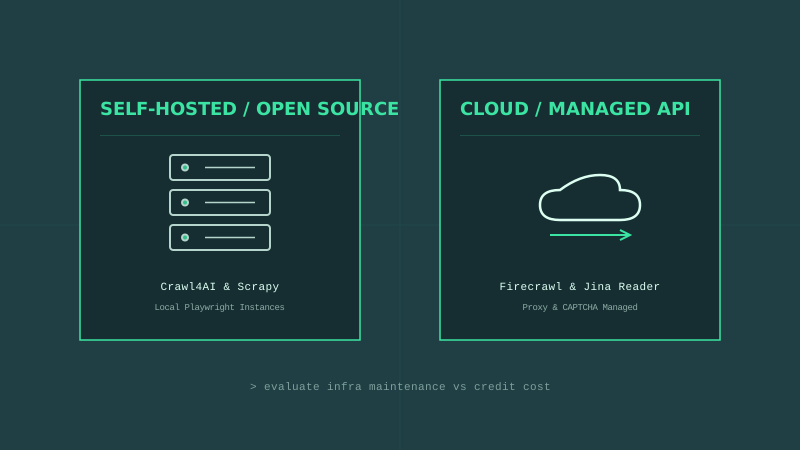
Should you self-host your headless browser cluster or pay for a cloud extraction API? We compare Crawl4AI, Firecrawl, Jina Reader, and Scrapy.
How to integrate NCBI's E-utilities API to retrieve structured medical research, journals, and metadata.
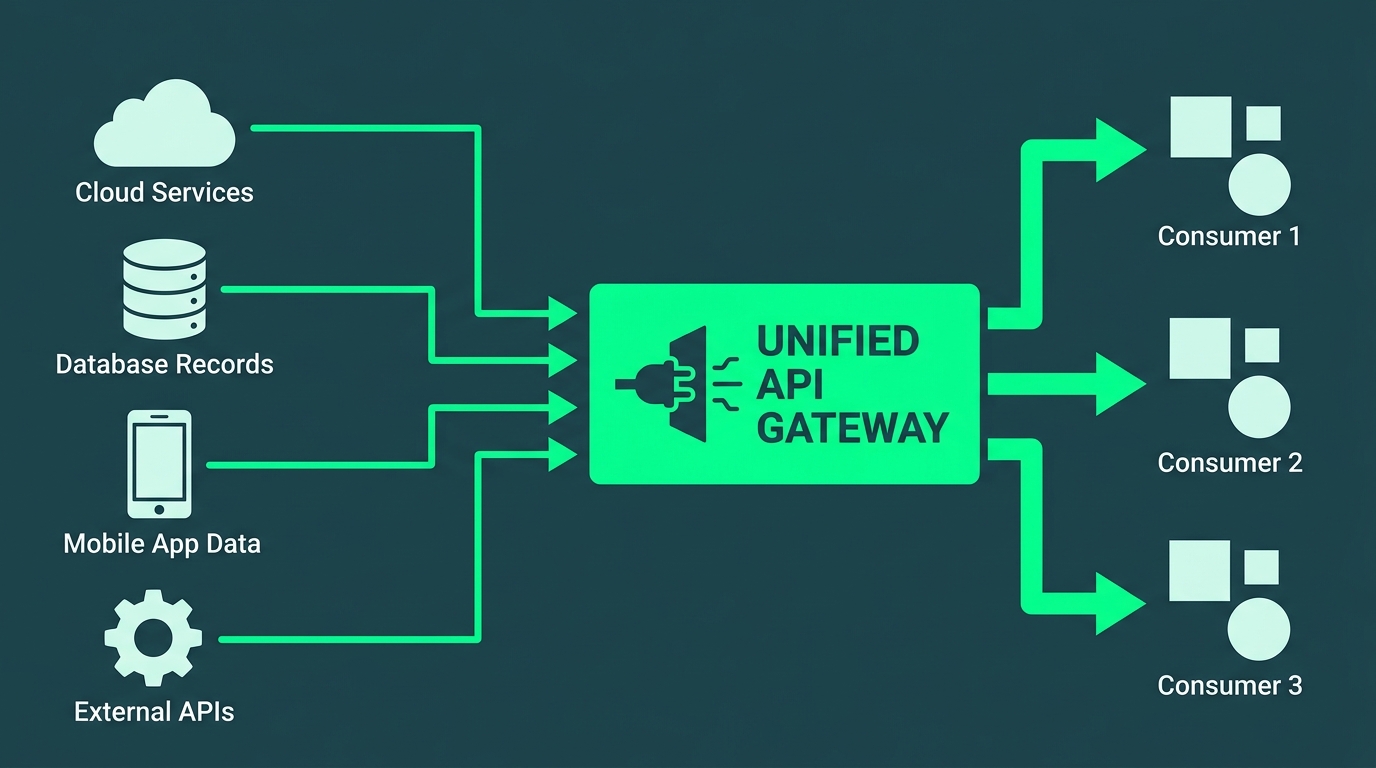
AI teams waste hours writing and maintaining custom scrapers and API integrations. Here is how to build a unified connector architecture.
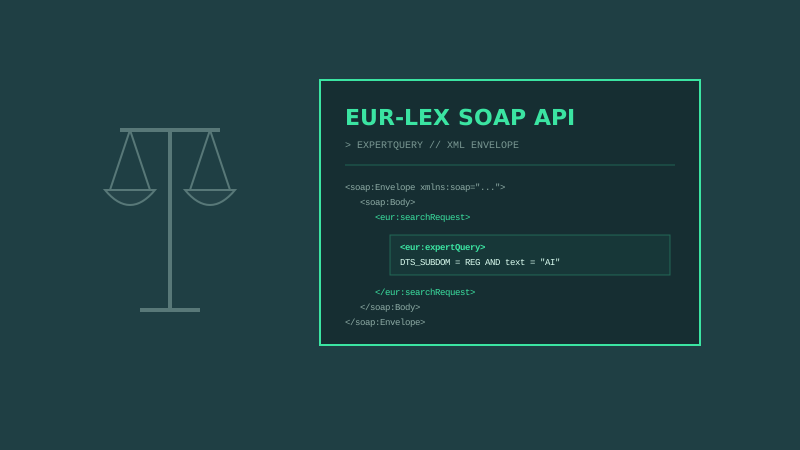
How to use the EUR-Lex web services API to search and retrieve structured European Union legislation and legal metadata.
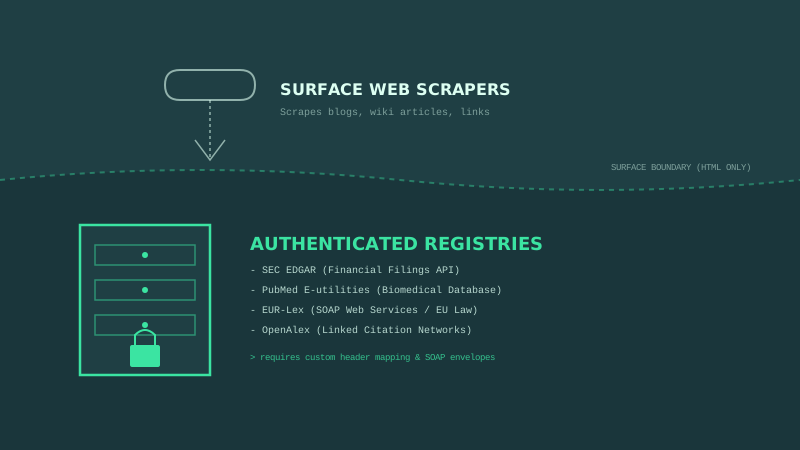
Why compliance, financial, and medical AI agents cannot rely on surface web crawlers, and how to query authoritative deep web registries directly.
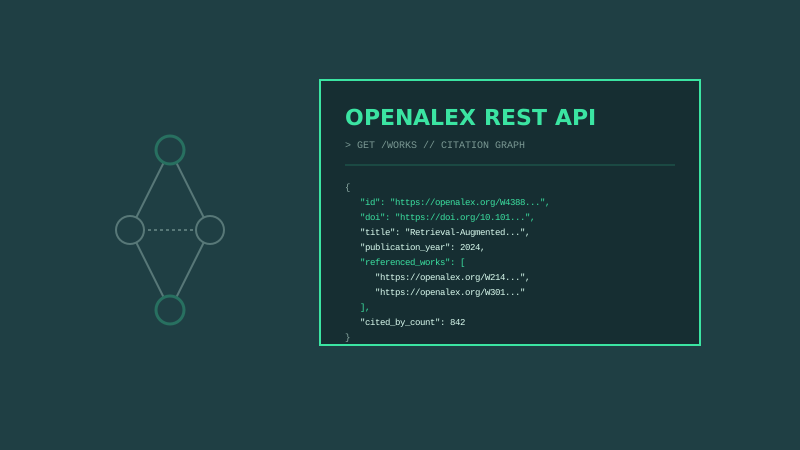
How to use the OpenAlex API to retrieve linked, structured metadata for 250 million scholarly publications.
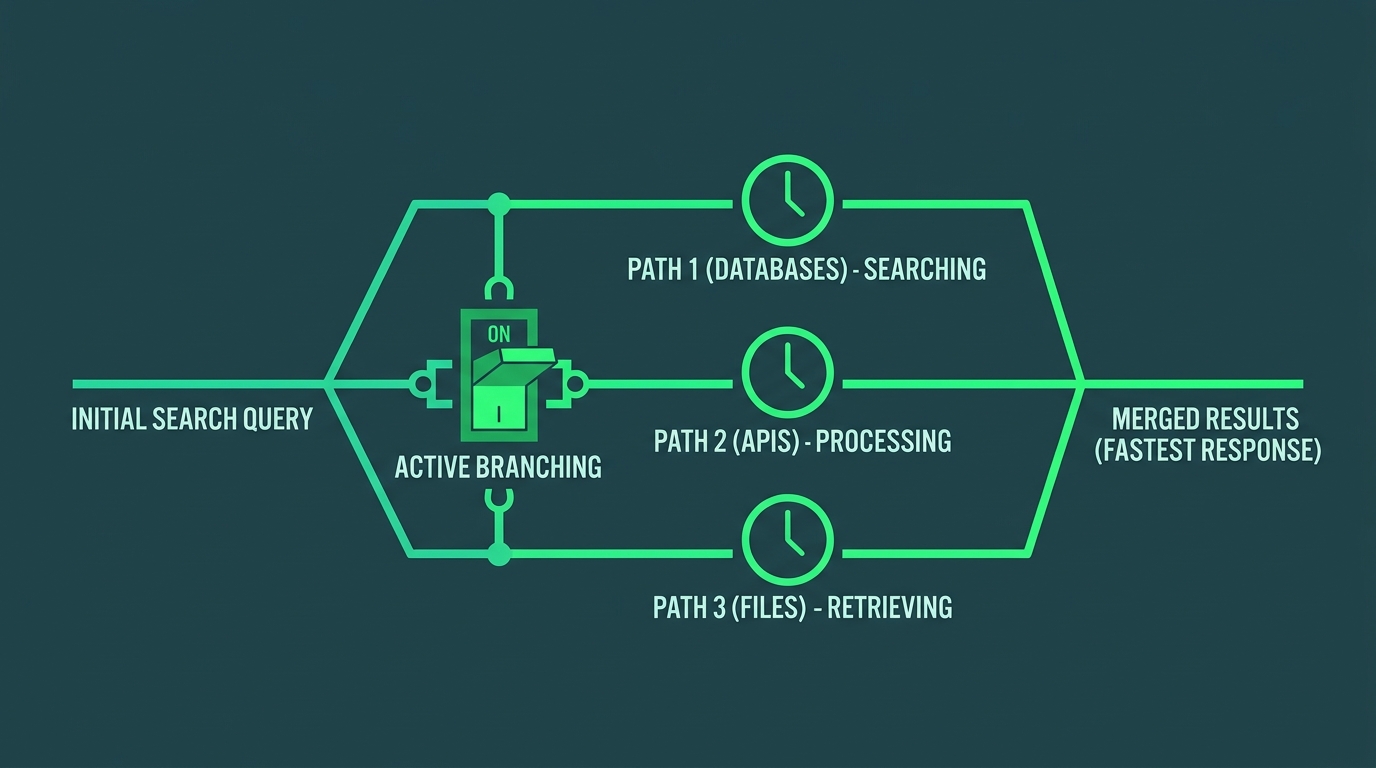
Federated search across multiple external APIs is highly sensitive to latency spikes. Here is how to build resilient parallel search queries.
A comprehensive developer platform designed to turn entire websites into structured JSON or clean Markdown in a single API call.